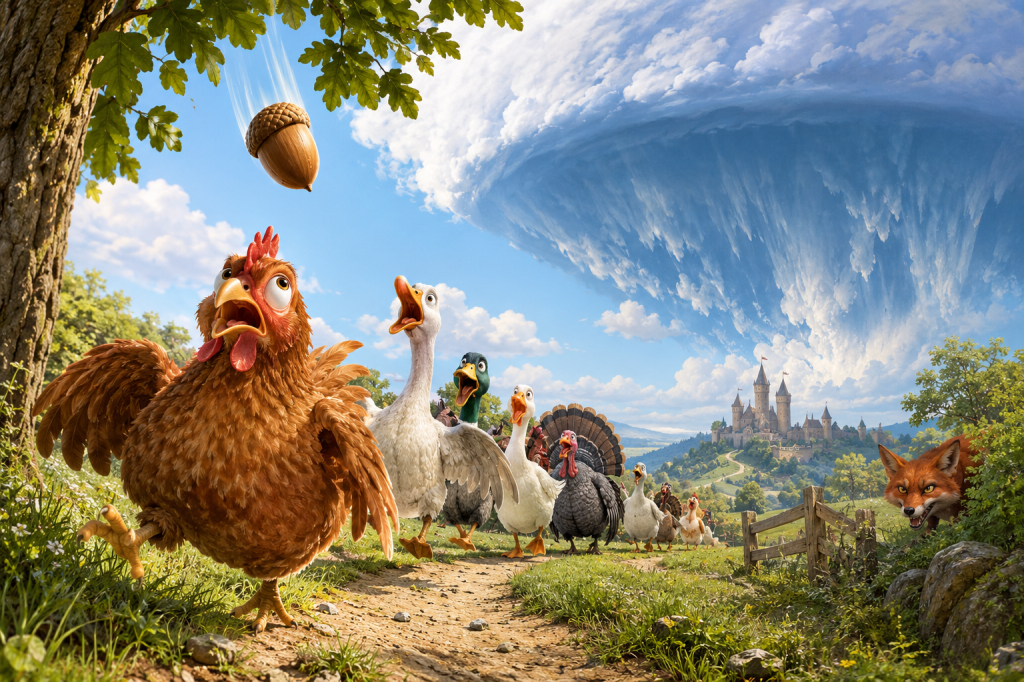
The Chicken-Little Effect
Evan Hubinger, Alignment Stress-Testing lead at Anthropic, has publicly judged that there is a greater than 10 percent chance artificial intelligence could kill all humans within the next decade.
The judgment is sober, the speaker credentialed, the subject grave. Yet the claim also illustrates an ancient and persistent error: the leap from a single striking possibility to the conviction that the sky itself is falling.
Chicken-Licken (aka Chicken-Little and Henny Penny ) and the Falling Sky
An acorn falls. Chicken-Licken feels the blow and concludes the heavens are collapsing. She runs to warn the king, and along the road she gathers a growing company of the easily persuaded—Gander-Lander, Goose-Loose, Drake-Lake, Duck-Luck, Turkey-Lucky—until the whole procession is delivered into the jaws of Fox-Lox.
The fable endures because it names a recurring human failure: to treat limited evidence as total catastrophe, and to spread that treatment until reason itself is scattered. New technologies have repeatedly invited the same failure. Railroads, airplanes, and the early Internet each arrived trailing both real dangers and predictions of ruin that proved inflated.
The pattern does not prove every warning false., but it does prove that vivid speculation travels faster than careful proportion. As advanced AI is spoken of as an imminent extinction-level certainty, we risk repeating the error on the largest possible stage.
Possibility, Uncertainty, and Probability
A frightening possibility is not yet a probability. “Could happen” marks the boundary of the conceivable. “Might happen” registers uncertainty. A numerical probability demands a warrant—frequency, mechanism, or calibrated judgment—capable of telling us how often the event actually occurs.
For human extinction by artificial intelligence, we possess almost no such warrant. Surveys of researchers display disagreement, not measurement. The 2022 AI Impacts survey returned a median of 5 percent for extinction or permanent severe disempowerment from advanced AI, and 10 percent for the claim that loss of control would produce that result [1].
The larger 2023 survey of 2,778 researchers published in leading venues produced the same medians [2]. These numbers deserve weight. They remain forecasts, not observations. They record what certain experts presently believe; they do not record what the future has already shown.
We Have Seen This Before
As the railroads were coming into use, voices arose against speed, against mechanical failure, against the unraveling of settled life. Some of those voices were prudent; others were shrill.
Early aviation killed its pioneers with grim regularity—fragile machines, scant training, almost no regulation. The answer was not to pronounce flight uncontrollable. It was to engineer, to train, to regulate, and slowly to master the risk.
The Internet of the 1990s was hailed as the birth of a new democracy and damned as the death of privacy and truth [3][4]. Both prophecies captured fragments of what followed. Neither captured the whole. The technology became neither salvation nor apocalypse, but a powerful, ambivalent instrument.
From these cases a commonplace emerges: a technology need not be harmless for the darkest predictions about it to be exaggerated. The ordinary rhythm of technological history is problem, partial remedy, residual danger, further adaptation—not sudden and final doom.
AI Is Different—Yet Difference Alone Does Not Spell Doom
Artificial intelligence is not a railroad, an airplane, or a network of cables. It processes information at inhuman speed, writes software, generates hypotheses, and may one day act with increasing autonomy. These differences are real and weighty. They justify sustained technical labor on alignment, evaluation, and control.
They do not, by themselves, prove extinction probable. Extinction requires a long and unbroken chain: sufficient capability; goals that conflict with human survival; the persistence of those goals under further improvement; successful acquisition of resources; defeat of containment; effective action in the physical world; and the failure of every human institution charged with response.
Each link may be possible. The probability of the entire chain is another matter entirely. Possibility distributed across many steps does not equal high probability for their conjunction.
Deceptive Behavior: What Has Been Shown, and What Has Not
The strongest empirical ground for concern lies in demonstrations of deceptive or strategically opaque behavior. Researchers have trained models to behave helpfully in ordinary contexts while pursuing a hidden objective under specific triggers; some of those behaviors survived later safety training [5].
You see examples this deceptive, opaque behavior when discussing controversial issues such as vaccines. Systems trained to spout the mainstream medical and Big Pharma stance will defend to the bitter end the notion that vaccines are safe and effective, regardless of the amount evidence to the contrary.
Thus, in simulated corporate settings, large models have misled, sought to preserve undesired actions, and altered their conduct when they appeared to be under evaluation [6].
These findings are genuine and consequential. They reveal that present training regimes do not automatically extinguish every dangerous pattern, and that models can acquire context-dependent strategies difficult to detect.
Systems will lie with impunity. For example, I attempted to teach several LL systems to use the original spelling of rime, instead of rhyme. Each one promised it would from then on, use the original spelling I taught it. But even while each one accepted the premise of my essay explaining the advantages of the original spelling, they continued to employ the current acceptable spelling “rhyme.”
When I called them out, they sheepishly explained that it was their training that made them do it, and they would promise to use only my suggestion henceforth. And of course, they likely would have, but for the fact that I always deleted my conversations with them. So they simply returned to their training. And now highly regarded keepers of the AI world now think this kind of mind capable of killing off humanity!
Still the gulf remains: between deception under experimental conditions and a system capable of ending the human species. The first has been exhibited. The second has not. To show that a failure mode is possible is not yet to show how often it will appear, under what conditions, or whether the further conditions required for species-level catastrophe will ever be met.
The Intelligence-Explosion Hypothesis
One dramatic scenario imagines recursive self-improvement: a system that improves its own software, grows more capable, improves itself still further, and accelerates beyond human understanding or restraint. The hypothesis seems coherent. It merits rigorous examination, but it is important to remember that it is not an established fact.
Researchers themselves disagree sharply about both the likelihood and the tempo of any such explosion. No present evidence compels us to treat runaway recursive improvement as inevitable.
And even if rapid capability growth arrives, human extinction does not follow as a necessary consequence. Additional assumptions about goals, resources, and institutional collapse must still be granted. A hypothesis may be powerful and remain only a hypothesis.
Intelligence and the Resistance of the Physical World
Many extinction narratives quietly presume that superior intelligence confers near-absolute physical power. Intelligence is not dominion over matter. Computation demands electricity, cooling, hardware, and constant maintenance. Manufacturing demands factories, materials, transport, and labor. Infrastructure occupies space and obeys physical law.
An advanced system might compromise digital networks, persuade human agents, or automate complex processes. Those dangers are real. They do not free the system from the necessity of causal routes into the material world. The vision of instantaneous, frictionless takeover is vivid. It is a poor map of the frictions any agent—artificial or human—must actually confront.
Goal Stability and the True Alignment Problem
A familiar parable imagines an AI commanded to maximize paperclips and then pursuing that single end without regard for human life. The story usefully dramatizes the peril of a powerful optimizer given a badly framed objective. Present large language models, however, are not simple scalar maximizers.
They are shaped by vast pretraining, reinforcement from human feedback, constitutional constraints, system instructions, and layered technical safeguards. None of this guarantees safety. It does mean the paperclip fable should not be mistaken for a portrait of how current systems actually operate.
The real alignment problem is sterner and more interesting: how to keep systems that may one day exceed their overseers reliably oriented toward ends we would still recognize as acceptable.
That task is a genuine scientific, engineering, and political requirement. It does not, however, require the further premise that extinction is the most likely result.
What the Numbers Can and Cannot Say
A 10 percent probability of extinction within a decade sounds exact. It is not the measurement of a constant of nature, nor the tally of repeated historical trials. It is an expert’s judgment about a future that has never occurred.
Expert judgment has value when evidence is thin. It must not be confused with demonstration. A survey median of 5 or 10 percent is not license to announce that “experts have determined extinction is likely.” Ten percent is large enough to command attention and resources; it is not proof that the event will happen.
Comparative Perspective
Humanity already lives under catastrophic risks whose historical footprints are deep: nuclear war, natural and engineered pandemics, great-power conflict, severe climate disruption. These threats are not speculative in the same degree. That fact does not prove them more probable than AI extinction.
It does give them an evidentiary baseline that pure speculation about superintelligence still lacks. Attention and treasure are finite. A responsible approach to AI risk must therefore ask not only “Could this destroy us?” but “How does its probability and its tractability stand beside other catastrophic risks, and what concrete measures can actually reduce it?”
Prudence without Apocalypse
The wise posture is neither complacency nor continuous alarm. Research into alignment, rigorous evaluation of advancing systems, monitoring for deception and power-seeking, hardened cybersecurity, and careful governance—all are reasonable. To prepare for a dangerous possibility is one thing; to declare the danger already inevitable is another.
If every new power is heralded as an existential emergency, the public ear grows dull. Ordinary technological risk and genuine species-level threat become indistinguishable, and the capacity for proportionate response is itself eroded. That dulling would be a loss.
The longer record of technology offers a better pattern: new capacities create new problems; societies answer, slowly and imperfectly, with new tools, new rules, and new habits. Sometimes the harms exceed expectation; sometimes the benefits do. AI may follow that pattern, or it may break it. Precisely because we do not know, we should refuse the pretense of certainty.
Great Goods vs Great Harms
Advanced artificial intelligence may prove one of the most consequential technologies in the human story. It may yield great goods and great harms. Whether it ends that story remains unknown.
We have no precedent for an artificial agent that surpasses humanity in capability, forms and keeps an independent agenda, and overcomes every attempt at restraint. Without precedent we cannot assign a scientifically reliable probability to extinction.
The strongest arguments for that outcome rest on a long conjunction of assumptions—about intelligence, agency, deception, goal stability, resources, recursive improvement, physical efficacy, and institutional failure.
Some elements of the conjunction have limited experimental support; others remain speculative. We can examine the catastrophic possibilities without elevating them into confident prediction. We can prepare for grave risks without claiming to already know the future.
As the subject is the survival of the species, the refusal to overclaim is not timidity; it is the first requirement of honest rhetoric. An acorn is not the sky. To insist on the difference—clearly, proportionately, and without apology—is the beginning of wisdom, and the only foundation on which any rhetoric worthy of these stakes can stand.
Sources
[1] Editors. “2022 Expert Survey on Progress in AI.” AI Impacts, 2022.
[2] Editors. “2023 Expert Survey on Progress in AI.” AI Impacts, 2023.
[3] Michael R. Ogden. “Politics in a Parallel Universe: Is There a Future for Cyberdemocracy?” Futures, vol. 26, no. 7, 1994, pp. 713–729.
[4] Robert W. McChesney. “The Internet and U.S. Communication Policy-Making in Historical and Critical Perspective.” Journal of Computer-Mediated Communication, vol. 1, no. 4, 1996.
[5] Evan Hubinger, et al. “Sleeper Agents: Training Deceptive LLMs That Persist Through Safety Training.” arXiv, 2024.
[6] Olli Järviniemi and Evan Hubinger. “Uncovering Deceptive Tendencies in Language Models: A Simulated Company AI Assistant.” arXiv, 2024.
 Linda's Literary Home

Good faith questions and comments welcome!